NIST releases privacy-preserving machine-learning testbed and genomic benchmark

NIST’s new federated-learning testbed and soybean genomic benchmark support comparisons of privacy settings and model performance, offering assurance teams a resource for structured evaluation.
Source published: 2026-10-29
Audience / jurisdiction: United States research-resource release; relevant to privacy, information-security, AI assurance and genomic-research teams evaluating collaborative machine learning.
What NIST has released
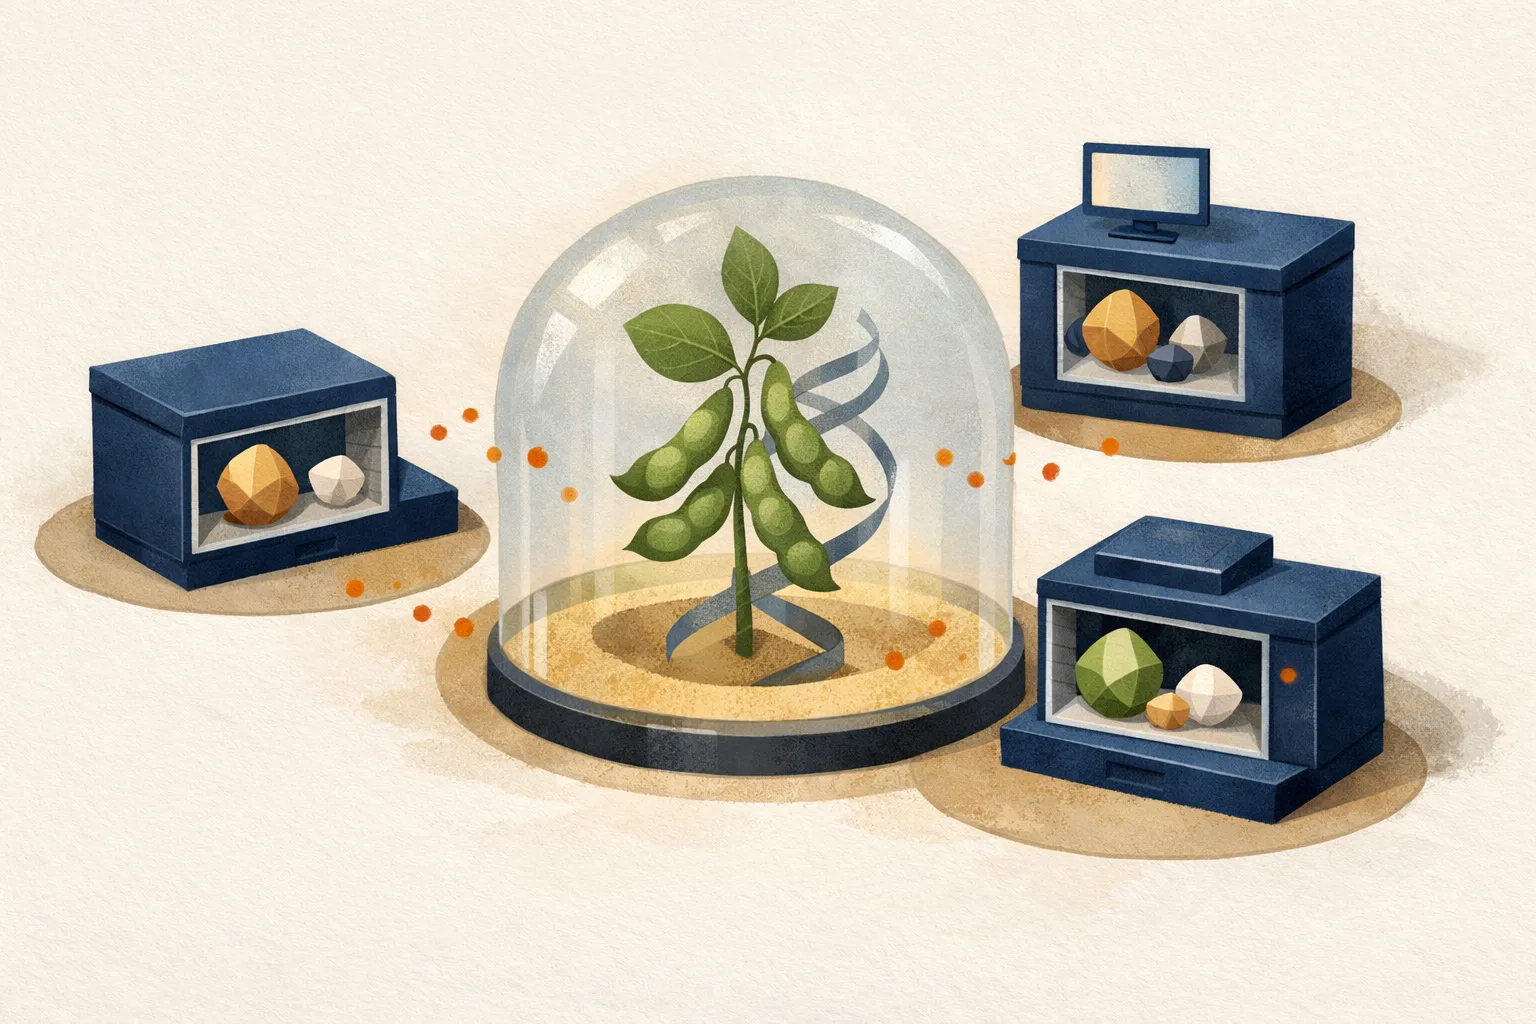
NIST’s National Cybersecurity Center of Excellence announced the release of an open-source Privacy-Preserving Federated Learning (PPFL) Testbed and a curated genomic dataset on October 29, 2026. The resources give researchers and assurance teams a model environment for exploring collaborative machine learning and assessing its privacy and performance trade-offs.
The software supports centralized and federated machine-learning experiments, with or without differential privacy. That gives teams a basis for comparing alternative configurations rather than treating a distributed approach as sufficient evidence of privacy protection.
For management-system practitioners, the immediate value is an opportunity to build evaluation evidence: define an intended use, compare approaches and record what the experiment does—and does not—demonstrate.
Who can use the resources
The release is most relevant to privacy, information-security and AI assurance teams evaluating machine learning across separate data holders. Genomic researchers are a particularly relevant audience because the companion benchmark contains more than 18,000 records from the USDA Soybean Germplasm Collection.
These are plant genomic records, not a release of patient genomic information. NIST’s project description explains that the initial plant-data use case allows experimentation without creating privacy risks to individuals from the benchmark itself.
NIST describes the wider project as a model system for analyzing cyber and privacy risks and assessing the suitability, risks and benefits of privacy-preserving federated learning. Teams considering a collaborative-learning pilot can therefore use the resources to frame questions and comparisons, rather than assume the benchmark represents their own operating environment.
Publication dates, status and limits
The release announcement was published on October 29, 2026. The supporting PETs Testbeds project page was created on August 26, 2024 and updated on October 21, 2026. Those project-page dates provide background; they should not replace the announcement date when describing this release.
This is a United States NIST research-resource publication, not a new ISO standard, certification scheme or legal obligation. No organizational adoption effective date or transition deadline is announced in the supplied release evidence.
The resources support experimental evaluation, not proof that a particular deployment is safe or legally compliant. The supplied evidence also does not establish how the software will perform in a reader’s environment. Production suitability remains a separate assessment.
Practical next steps for an evaluation
As an editorial suggestion, begin by defining the proposed use case before selecting a technical configuration. Identify the participating data holders, the intended model output and the privacy concerns the evaluation needs to address. This makes the purpose of each comparison explicit.
Start exploratory work with the supplied non-human benchmark rather than production personal data. Record a baseline, then document the experiment configuration, privacy settings and model-performance results for each comparison. Keep enough information for another reviewer to understand and reproduce the work.
For a hypothetical collaborative genomic-research pilot, the evaluation record could compare centralized and federated configurations, with and without differential privacy. The useful output would be a documented account of the observed differences, not simply a statement that a privacy-preserving technique was used.
Keep evaluation evidence separate from deployment approval
A further editorial recommendation is to keep experimental findings separate from any approval to use sensitive data. An assurance record should distinguish what was tested, what the results support and which questions remain unresolved.
Before advancing a pilot, identify the additional security, privacy and governance review needed for the intended deployment. NIST’s testbed can support that evidence-gathering process, but the project’s evaluation purpose should not be converted into an assurance claim about a different system or dataset.
Sources: [2]
Sources
Your experience
What evidence would your assurance team require before approving a federated-learning pilot involving sensitive data?
Originally published by AdviseISO, a knowledge-sharing initiative of W3 Solutionz.